Career Opportunities in Data Annotation
A common myth is that data annotation is a monotonous manual labor limited to simple bounding boxes around obvious objects. In reality, the rapid development of computer vision, robotics, and generative models has turned labeling into a complex discipline requiring a deep understanding of model context. Modern annotation requires spatial reasoning, attention to detail, and specialized domain knowledge – making human expertise the primary success factor for artificial intelligence.
Quick Take
- Data annotation has transformed into a strategic IT profession where humans act as the primary AI trainers.
- No programming skills are required to start – attention to detail, strict adherence to guidelines, basic English, and digital literacy are sufficient.
- Working on modern annotation platforms allows you to leverage auto-annotation and work with complex 3D LiDAR and multimodal data.
- You can build your own team and independently master annotation platforms or join experienced market players.
What is Data Annotation?
From the outset, artificial intelligence models do not understand the physical world, human language, or spatial relationships. At its core, data annotation is the process of applying informative labels to raw, unstructured data, through which machine learning algorithms learn to recognize patterns, establish decision boundaries, and make accurate predictions.
The Spectrum of Modern Data Labeling
When specialists label objects, tag text, or calibrate spatial coordinates, they create what is known as ground truth. This is a benchmark dataset against which the neural network compares its predictions during training, corrects errors, and adjusts its internal weights.
Depending on the data type and machine learning tasks, annotation covers several key areas:
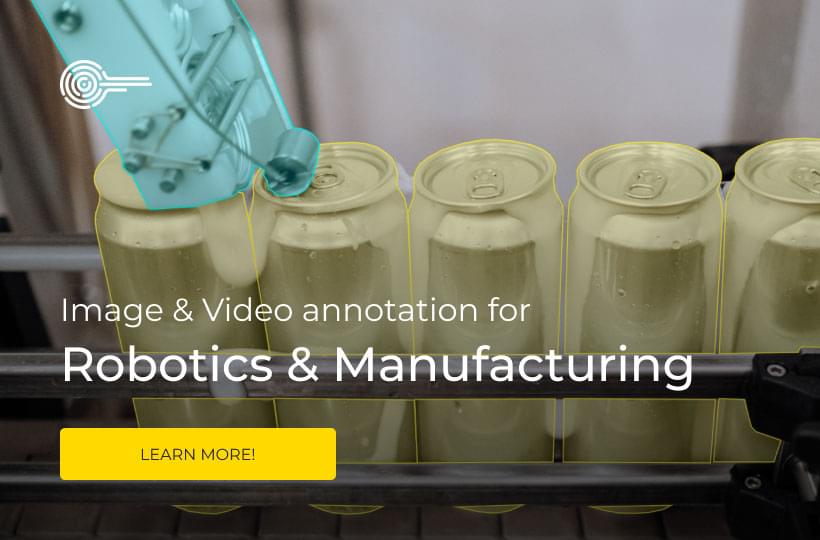
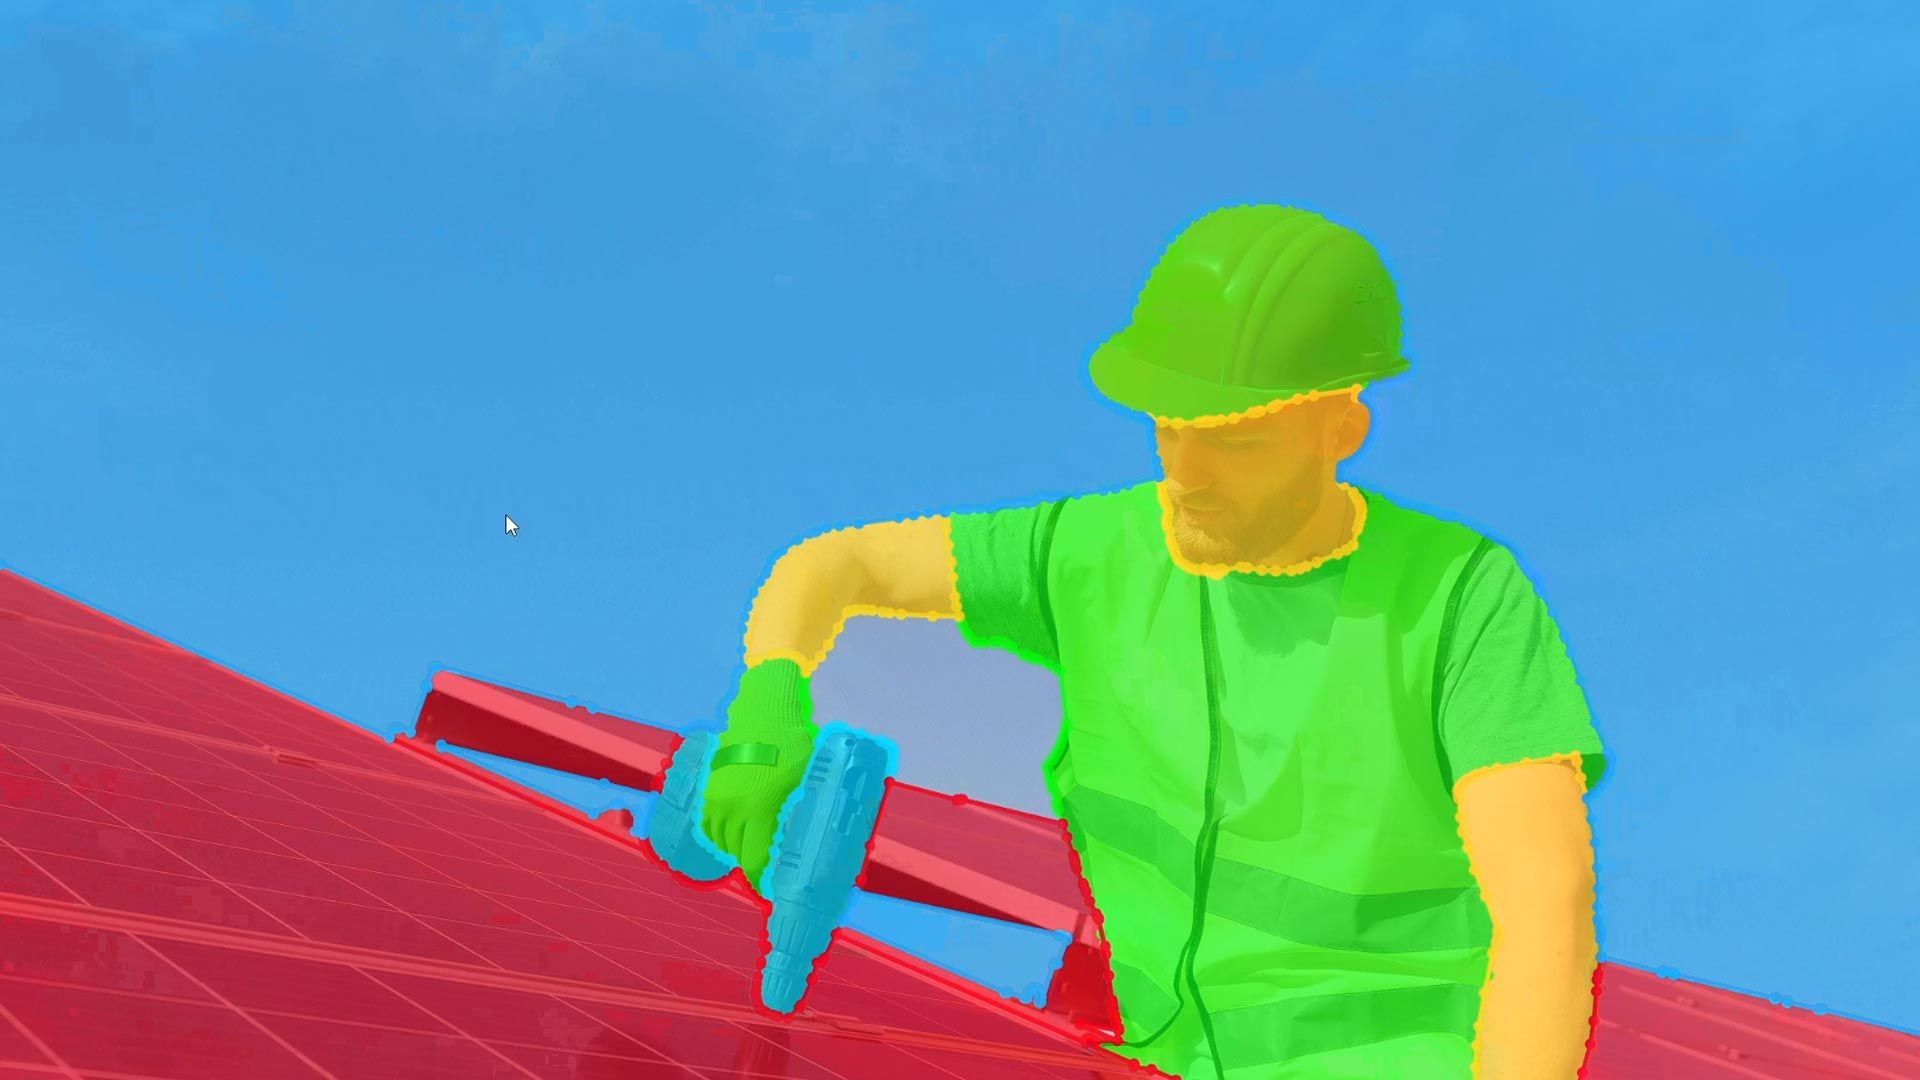
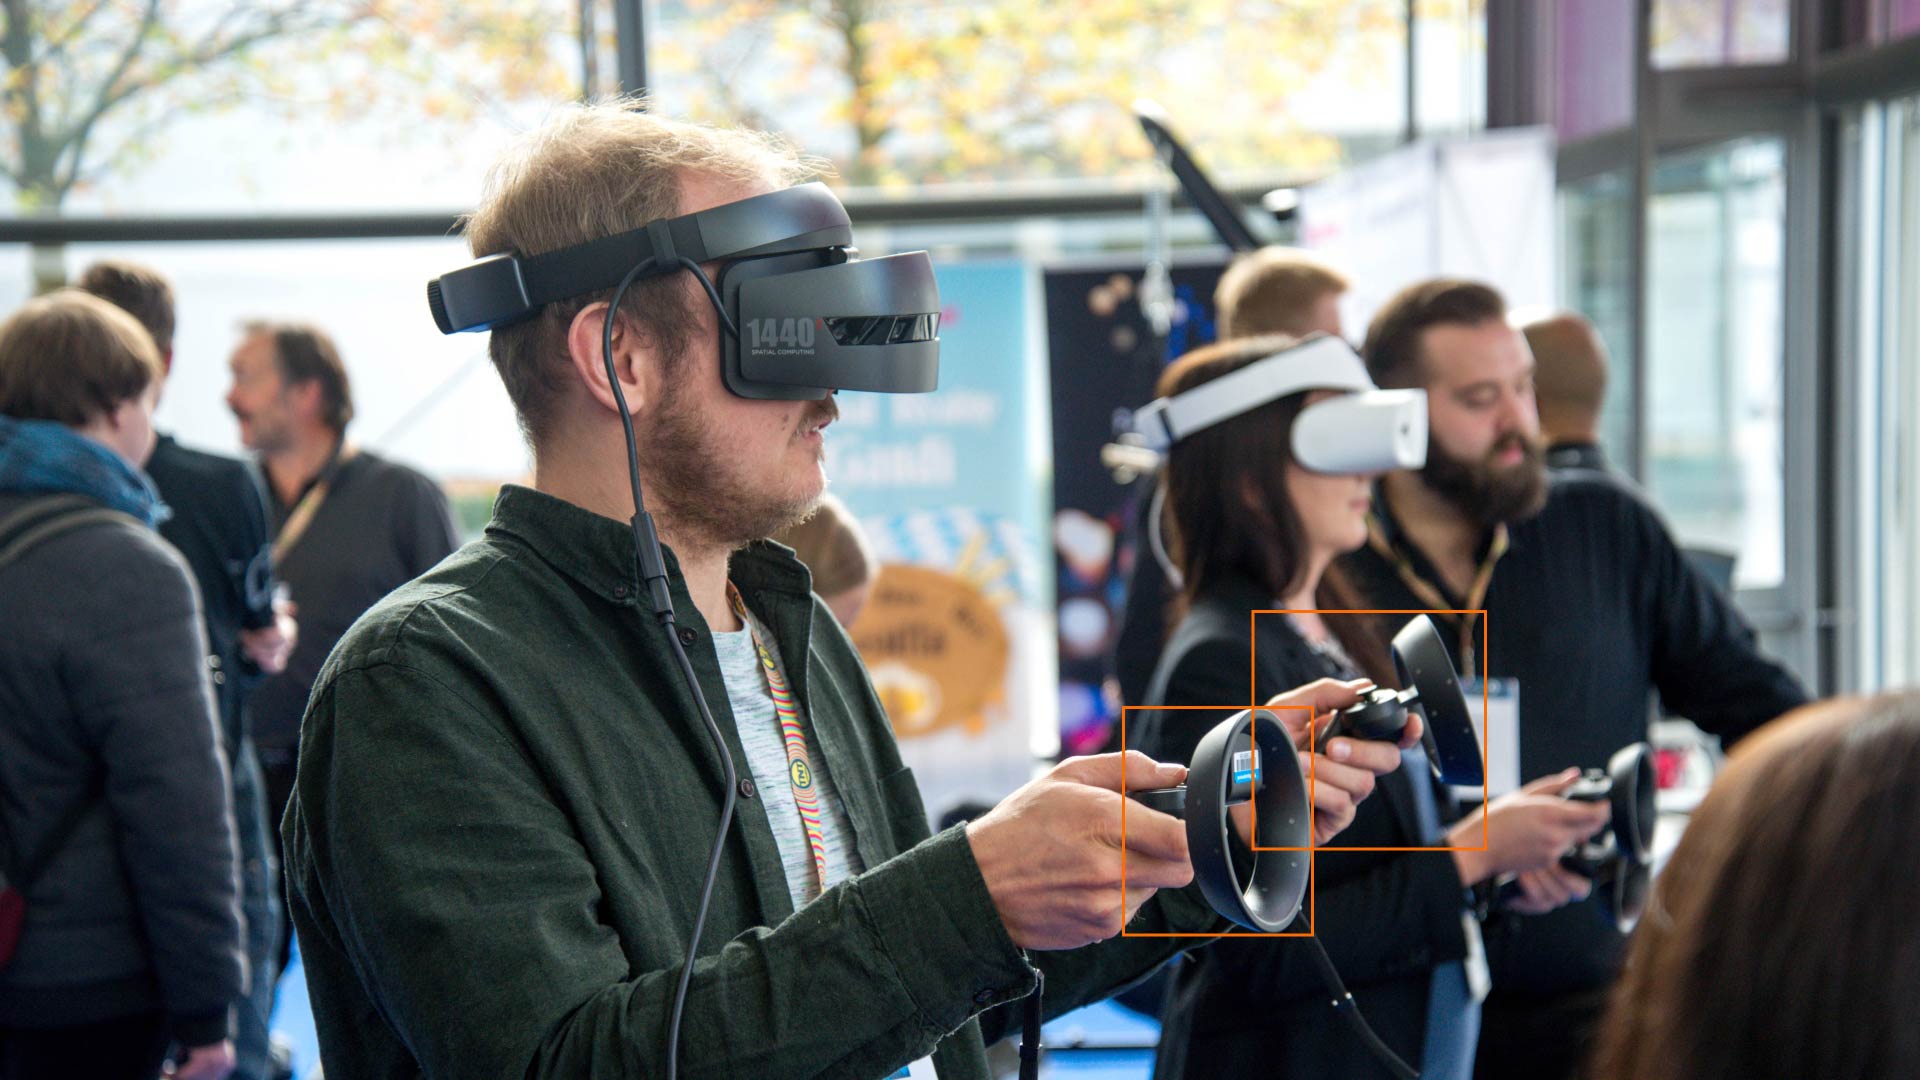
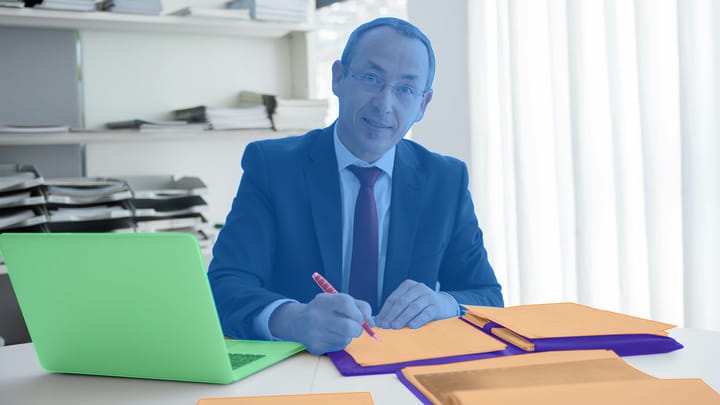
- Images: from outlining objects with 2D bounding boxes and detailed contouring (polygonal and semantic segmentation) to classifying overall frame attributes.
- Video: tracking dynamic objects from frame to frame, motion interpolation, and timestamping event boundaries.
- Text: document categorization, sentiment analysis, user intent identification, entity extraction, and establishing semantic connections.
- Audio: speech-to-text transcription, acoustic noise suppression, speaker diarization, and phonetic segment labeling.
- LLM & Generative AI: model response evaluation, preference ranking, safety red-teaming, and RLHF.
- Multimodal AI: pairing and synchronizing different data types simultaneously – for example, linking a text description to specific video segments or fusing data from multiple cameras.
Data Annotation for Beginners
Starting in data annotation does not require writing code or having a formal education in data science. The primary task of an annotator is to become the "eyes and brains" for the neural network, providing it with high-quality, precise data.
Basic Skill Set to Get Started
The entry barrier into the profession is indeed accessible, but the quality requirements remain high. Here are the key skills that employers and MLOps teams look for:
- Attention to Detail and Consistency. A model quickly overfits or makes errors if the same object is labeled differently. The ability to maintain focus over long periods is key to success.
- Ability to Strictly Follow Guidelines. Every project comes with dozens of pages of instructions. Strict compliance with labeling rules takes precedence over personal assumptions.
- English Language. Most international projects, technical documentation, and orders from AI labs require an A2–B1+ level to read guidelines, and B2+ for working with text and LLMs.
- Basic Computer Literacy. Confident PC user skills, understanding how to work with browser tools, hotkeys, and file systems.
- Specialized Knowledge. A background in medicine, law, linguistics, or agronomy serves as a powerful advantage for high-paying, niche projects.
- Readiness for Qualification Tests. Most platforms include a test assignment stage to evaluate accuracy before granting access to real datasets.
Career Paths in Data Labeling
This ecosystem offers specialists and teams two flexible scenarios for career and business growth:
- The Independent Path and Team Building. You can independently master modern annotation platforms, learn automation tools, build your own distributed groups, and execute turnkey projects or support your own AI startups.
- Joining Experienced Market Players. Another path is to join established professional teams at companies like Keymakr. This allows you to work immediately with complex datasets for leading global brands, receive a stable task flow with ready-made management, and grow quickly under the guidance of strong QA leads.
The modern approach to labeling management is a complete operating system that combines recruiting, project-specific training, multi-tiered QA control, and work with cutting-edge software.
Data Annotation Outsourcing
Understanding why the demand for annotation specialists arises provides a clear picture of the data annotation jobs market. For many AI companies and model developers, building their own labeling teams from scratch is financially and operationally impractical.
Forming an in-house team requires massive expenditure on hiring, infrastructure, and management, which distracts from the main goal – developing the neural network architecture itself. That is why the machine learning ecosystem relies on specialized providers and distributed workforces.
Key Reasons for Labeling Outsourcing
Leveraging external teams and outsourcing partners solves several business objectives:
- Rapid Scale and Launch. When training a model urgently requires hundreds of thousands of labeled frames, outsourcing allows deploying a team of hundreds of annotators in a matter of days.
- Global and Linguistic Reach. Training multilingual LLMs or localized computer vision algorithms requires native speakers of rare languages and people from different parts of the world.
- Access to Niche Experts. Instead of maintaining a staff of doctors or lawyers, companies engage specialized external groups to annotate medical imaging or analyze contracts on a project basis.
- Quality Control. Experienced providers take on the full cycle of data accuracy verification, guaranteeing compliance with the targeted coverage level.
How to Build a Career in Data Annotation
If you are considering this direction as a starting point in the IT industry, follow a clear career growth strategy:
- Understand the Core Processes. Master the terminology of computer vision, NLP, and basic labeling methods.
- Start with Accessible Projects. Gain your first practical experience on basic 2D classification or text tagging tasks.
- Master Innovative Tools. Learn to work on professional platform solutions (for example, our company uses Keylabs) to master auto-annotation, 3D data handling, and tracking your own accuracy metrics.
- Build Accuracy and Systemic Consistency. Establish a reputation as a specialist who avoids errors in complex edge cases.
- Try New Modalities. Move from photos to video, 3D LiDAR, and evaluate large language model responses.
- Develop Domain Expertise. Apply your knowledge from background fields.
Data annotation doesn't have to be your final destination. It can serve as your most powerful launchpad into the world of artificial intelligence.
FAQ
How long does it take to master basic annotation skills?
The basic principles of 2D labeling or text classification can be learned in a few days. However, working with complex modalities or advancing to QA/Lead positions will require several months of practice.
What is the difference between working as a freelancer and working as a labeler in a specialized company?
A freelancer independently searches for projects and masters tools, whereas working in specialized companies provides a stable task flow, established management, access to complex enterprise datasets, and professional growth under the guidance of strong QA leads.
Which industries offer the highest-paying data labeling projects?
The highest rates are offered by projects in autonomous vehicles (working with 3D LiDAR), medical diagnostics (CT/MRI scan segmentation), law, and large language model development (RLHF and safety red-teaming).