Best Datasets for Training Semantic Segmentation Models
Choosing the right dataset is the single most critical decision when developing high-precision computer vision systems. Whether you are building algorithms for autonomous driving, satellite analytics, or medical diagnostics, it is the quality and structure of ground-truth data that dictate how well your model will generalize in real-world environments.
This guide to semantic segmentation takes a detailed look at the best open benchmarks, key criteria for data evaluation, and the specifics of their application for training models.
Quick Take
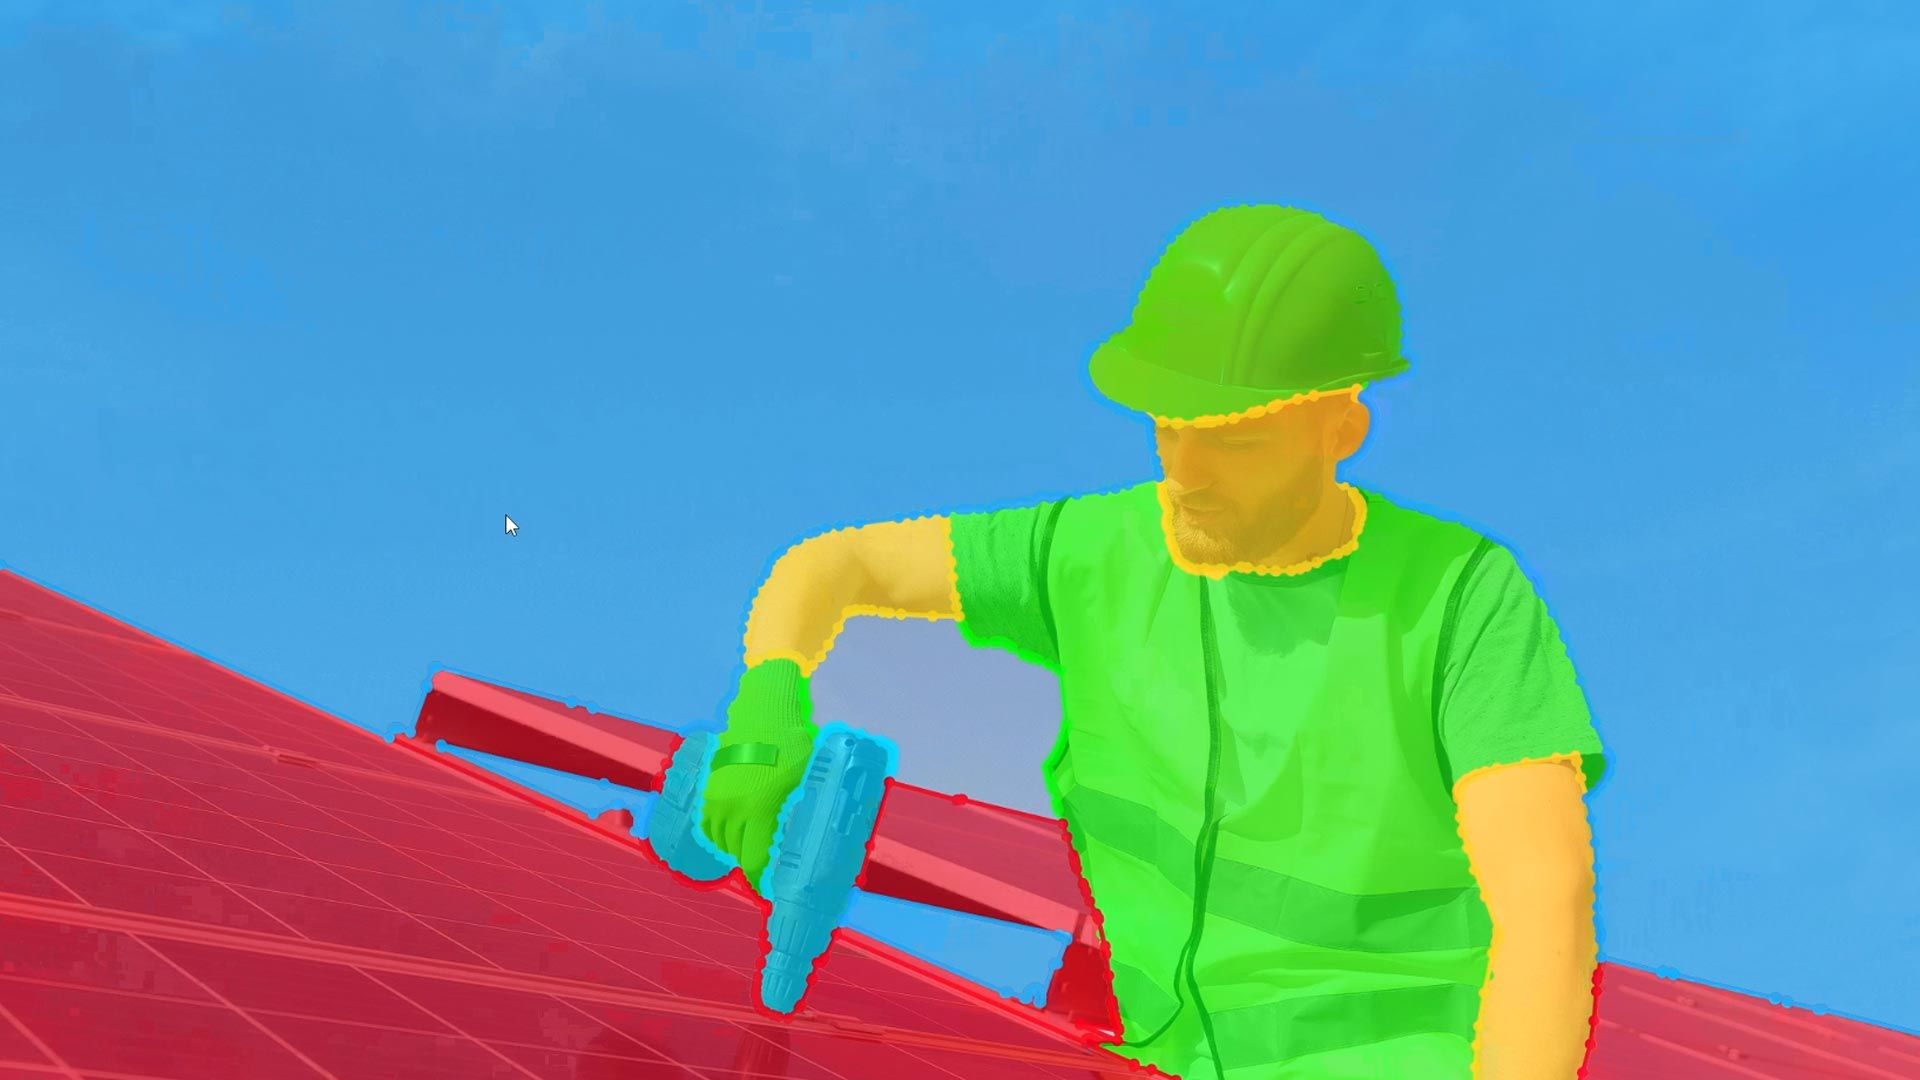
- Semantic segmentation classifies every pixel of an image, creating a continuous color map of classes without splitting them into separate object instances.
- Cityscapes is the gold standard for urban autopilot (ADAS), but it is limited to fair European weather.
- COCO is a versatile choice for pre-training models, but features smoothed, less precise mask contours.
- PASCAL VOC is a compact benchmark for fast scientific tests; it is outdated for modern production.
- ADE20K is ideal for indoor robotics and scene parsing, but suffers from high class imbalance regarding rare objects.
- A custom dataset is necessary when working with non-standard optics (thermal imagers, fisheye lenses), specific defects/diseases, rare weather conditions, or strict NDA requirements.
What is Semantic Segmentation?
Before diving into dataset analysis, let us clarify the core definition. Semantic segmentation is a deep learning approach where every individual pixel in an image is assigned a specific class label (for example, road, pedestrian, sky, vegetation). Unlike object detection, which merely outlines items with rectangular bounding boxes, semantic segmentation generates a continuous pixel map.
Because this technique classifies both background elements and distinct items, it establishes the foundation for semantic segmentation models (such as U-Net, DeepLabV3+, SegFormer, and Mask2Former) to operate.
Overview of Open Datasets
To choose the right dataset for training models, it is essential to examine it through the lens of three questions: what problem are you solving, how exactly will this dataset help the neural network, and what critical barriers will you encounter in practice.
Cityscapes Dataset
Use Case: Development of autopilot systems (ADAS), autonomous delivery robots, and urban infrastructure monitoring.
Why Choose It: It is one of the most accurate benchmarks for urban scenarios. It contains 5,000 frames with pixel-perfect, high-resolution annotation and 20,000 additional coarsely annotated frames from 50 European cities. The dataset thoroughly conveys street geometry, road surfaces, sidewalks, and associated urban objects.
Limitations: Geographical and climatic narrowness. All frames were captured predominantly in Western and Central Europe during dry, clear weather. It completely lacks extreme conditions: snow-covered roads, heavy downpours, night drives, fog, or distinct road markings and signs from other continents (such as Asia or North America).
COCO (Common Objects in Context)
Use Case: Pre-training universal neural networks and developing general computer vision systems.
Why Choose It: One of the largest and most popular datasets in the world, boasting over 330,000 images. It covers 80 distinct object categories and 91 background categories. Thanks to its vast diversity of scenes, it ideally trains the foundational layers of a neural network to recognize items in unstructured, real-world environments.
Limitations: Simplified contour detailing. Because COCO was created as a general benchmark for a wide range of tasks, object masks often feature smoothed, generalized polygons. It is not suitable for high-precision industrial or medical segmentation where millimeter accuracy of every boundary is paramount.
PASCAL VOC
Use Case: Rapid testing of new neural network architectures, academic research, prototyping, and establishing baselines.
Why Choose It: A classic and very compact benchmark (~11,500 images across 20 main categories) with strictly standardized samples. Due to its small size, it allows developers to quickly train and test models and easily compare their accuracy with published research results.
Limitations: Small volume and obsolescence for modern production. It is impossible to train a production-ready model solely on PASCAL VOC – the neural network overfits quickly and demonstrates low accuracy on live video feeds from modern cameras.
ADE20K
Use Case: Full scene parsing, indoor navigation for domestic and industrial robots, and 3D interior modeling.
Why Choose It: One of the most complex datasets in the field, created at MIT. It contains over 20,000 densely annotated images where absolutely every pixel of the frame is assigned to one of 150 classes (ranging from large furniture to small decor items and landscape features).
Limitations: Severe class imbalance and model convergence difficulty. Due to the vast number of small or rare categories (e.g., vase, clock, pillow), neural networks struggle to achieve high accuracy without complex loss function tuning and data balancing.
When Do You Need a Custom Dataset?
Open benchmarks are excellent for testing hypotheses, training base weights, and academic comparisons. However, in real-world business, the moment to build a custom dataset arrives almost immediately after exiting the PoC stage.
Main reasons to switch to a custom dataset
- Specific Hardware and Angles. Public datasets are gathered using standard cameras. If your system uses thermal imagers, medical endoscopes, fisheye lenses, or cameras mounted on a drone's dome, open data will fail due to optical distortions.
- Unique Classes and Defects. No open dataset contains annotations for micro-cracks on concrete structures, specific component defects on a conveyor belt, or particular agricultural leaf diseases.
- Edge Cases and Weather Conditions. Safe operation of an autopilot or robot requires frames with fog, lens dirt, sun glare, or snowstorms – edge cases virtually absent in standard public samples.
- Legal Compliance and NDA Requirements. Using open datasets in commercial products is frequently restricted by licenses.
How to Rapidly Build a Custom Dataset
Creating a custom dataset for semantic segmentation is the least automated and most resource-intensive type of labeling in computer vision, as every pixel in the frame must be assigned to a specific class. To provide clients with a high-precision dataset without massive time expenditure, we break the process down into three sequential stages:
- AI Pre-annotation:Instead of manually contouring every complex object from scratch, multimodal foundation segmentation models embedded directly into our proprietary platform are utilized. They automatically pick up contrasting edges and generate initial mask drafts.
- Pixel Correction with Precision Contouring Tools:Annotators refine and detail the AI-generated masks using specialized tooling:
- Magnetic Polygons. Automatically snap to gradient drops and contrasting object edges (e.g., between a car body and the asphalt).
- Smart Brushes. Allow smooth background areas to be painted over while accounting for texture and color segmentation of neighboring pixels.
- Layer Logic. Prevents masks from overlapping one another, ensuring that no pixel belongs to two conflicting classes simultaneously.
- Multi-Tier Quality Control and Pixel Metrics:Because minor errors along mask boundaries significantly reduce the model's final mIoU, annotation quality is audited algorithmically:
- Inter-Annotator Agreement Check. Comparing masks created by different annotators on the exact same frame using Intersection over Union (IoU) calculations.
- Automated Topology Validation. Algorithmic detection of missed pixels, isolated labeling artifacts, and improperly closed polygons.
This hybrid approach allows developers to quickly transition from baseline models trained on open data to highly specialized systems trained on precise masks tailored to specific business requirements.
FAQ
What is mIoU, and how does this metric measure dataset and model quality?
mIoU (mean Intersection over Union) is the primary accuracy metric in segmentation. It calculates the area of overlap between the predicted mask and the ground-truth annotation, divided by the area of their union. The more precisely object boundaries are labeled in a dataset, the higher the potential mIoU of the final model.
Can open datasets be used in commercial products?
It depends on the specific dataset's license. Some open samples are distributed under CC BY 4.0 licenses (allowing commercial use with attribution), while others carry strict Non-Commercial Use Only restrictions (strictly for research and educational purposes). For commercial products, it is safer to create proprietary datasets or thoroughly audit the legal status of each benchmark.
How does synthetic data help in training segmentation models?
Synthetic data generated in 3D engines provide 100% accurate pixel annotations without human labor. They are ideal for simulating rare conditions (night downpours, emergency situations), though they are typically combined with real-world data to prevent drops in model accuracy when deployed in the real world.
What is zero-shot segmentation, and how does it speed up data labeling?
Zero-shot segmentation allows an algorithm to instantly highlight the contours of any object based on a text query or a mouse click without prior training on that specific class. This enables the generation of accurate draft masks in seconds, leaving annotators with only the role of quality control and final refinement.
How can a semantic segmentation model be trained using available datasets?
Semantic segmentation models can be trained using deep learning frameworks such as TensorFlow and Keras. The datasets should be divided into training and validation sets for evaluation. Techniques such as data augmentation, hyperparameter tuning, and regularization can be used to optimize the model’s performance.